AHs ’24 · 2024
FastPerson
Enhancing Video-Based Learning through Video Summarizationthat Preserves Linguistic and Visual Contexts
話している内容も、画面の図や文字も使って、講義動画を短くする。Shorter lecture videos that account for both speech and on-screen information.
1 The University of Tokyo 2 Sony CSL Kyoto
The Augmented Humans International Conference · April 4–6, 2024 · Melbourne, VIC, Australia
研究の概要Overview
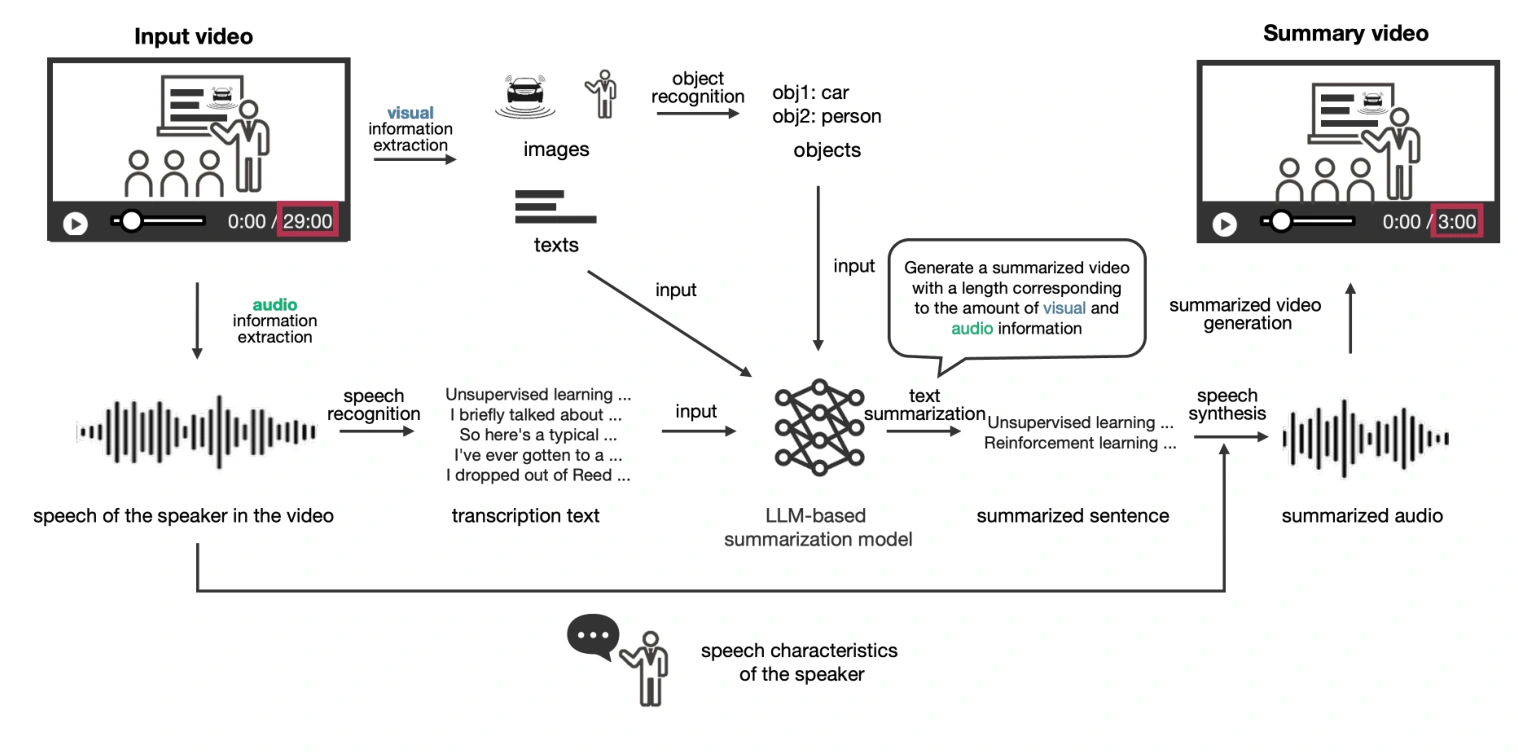
講義では、先生の説明とスライドや板書の両方が大切です。FastPersonは、音声の文字起こし、画面上の文字、写っているものを合わせて要約し、短い説明音声と元動画の映像から要約動画を作ります。詳しく知りたい章では元の動画へ切り替えられます。
Lecture videos communicate through narration, slides, and diagrams. FastPerson combines speech transcripts, on-screen text, and detected visual objects to generate chapter summaries. Synthesized narration and footage from the original form a shorter video, while chapter-level switching lets learners return to the original for detail.
どのように動くかHow it works
- 場面の変化や無音部分を手がかりに、動画を章に分けます。
- 話し言葉、画面の文字、物体の情報をまとめ、大規模言語モデルで章ごとの要約を作ります。
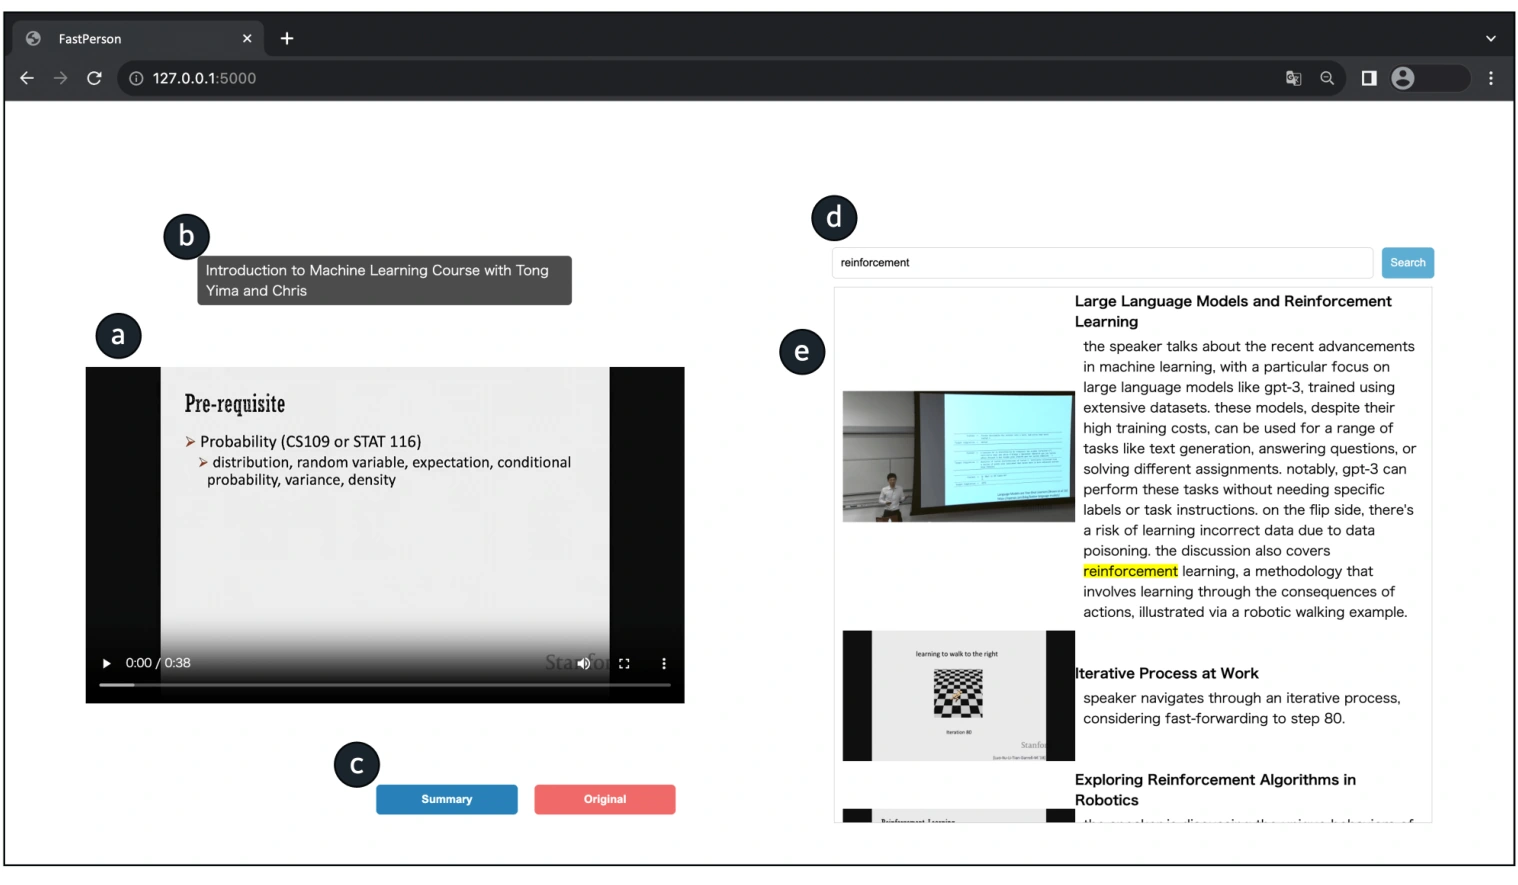
- 元の話者の声の特徴を使った要約音声を映像と組み合わせます。視聴者は、章ごとに要約版と元動画を切り替え、一覧や検索から見たい部分を選べます。
- Segment the lecture using scene changes and silence.
- Combine transcripts, OCR text, and visual-object information in an LLM-generated summary.
- Create summary narration using the original speaker’s voice characteristics and pair it with original footage. Offer chapter browsing, search, and summary/original switching.
何が分かったかFindings
- 平均視聴時間を約53%減らせました。40人をFastPerson群19人と通常の動画プレイヤー群21人に分け、同じ2本の講義動画で比較しました。1本目は平均16分43秒から7分49秒へ、2本目は22分32秒から10分34秒へ短縮されました(53.24%・53.11%削減)。
- 短時間の視聴でも、クイズ成績に統計的に有意な差はありませんでした。平均正解率は、1本目が通常70%・FastPerson71%、2本目が通常63%・FastPerson67%でした。今回の2動画では、見る時間を短くしても、内容理解を測るテスト成績の低下は確認されませんでした。
- Mean viewing time decreased by about 53%. Forty participants used either FastPerson (19) or a conventional player (21) for the same two lecture videos. Mean time fell from 16 min 43 sec to 7 min 49 sec for the first video, and from 22 min 32 sec to 10 min 34 sec for the second—reductions of 53.24% and 53.11%.
- Quiz performance showed no statistically significant difference despite the shorter viewing time. Mean accuracy was 70% with the conventional player versus 71% with FastPerson for the first video, and 63% versus 67% for the second. In these two videos, shorter viewing was not accompanied by a detectable decline in the comprehension quiz scores.
引用Citation
@inproceedings{kawamura2024fastperson,
  title = {FastPerson: Enhancing Video-Based Learning through Video Summarization that Preserves Linguistic and Visual Contexts},
  author = {Kazuki Kawamura and Jun Rekimoto},
  booktitle = {The Augmented Humans International Conference},
  year = {2024},
  publisher = {Association for Computing Machinery},
  doi = {10.1145/3652920.3652922}
}本文と図は上記の原著論文に基づきます。図をクリックすると拡大できます。Text and figures are based on the original paper linked above. Select a figure to view it at full size.