AHs ’23 · 2023
AIx Speed
Playback Speed Optimization Using Listening Comprehensionof Speech Recognition Models
一律の倍速ではなく、声の聞き取りやすさに合わせて細かく速度を変える。Adjusting playback speed moment by moment, guided by speech intelligibility.
1 The University of Tokyo 2 Sony CSL Kyoto
Augmented Humans Conference · March 12–14, 2023 · Glasgow, United Kingdom
研究の概要Overview
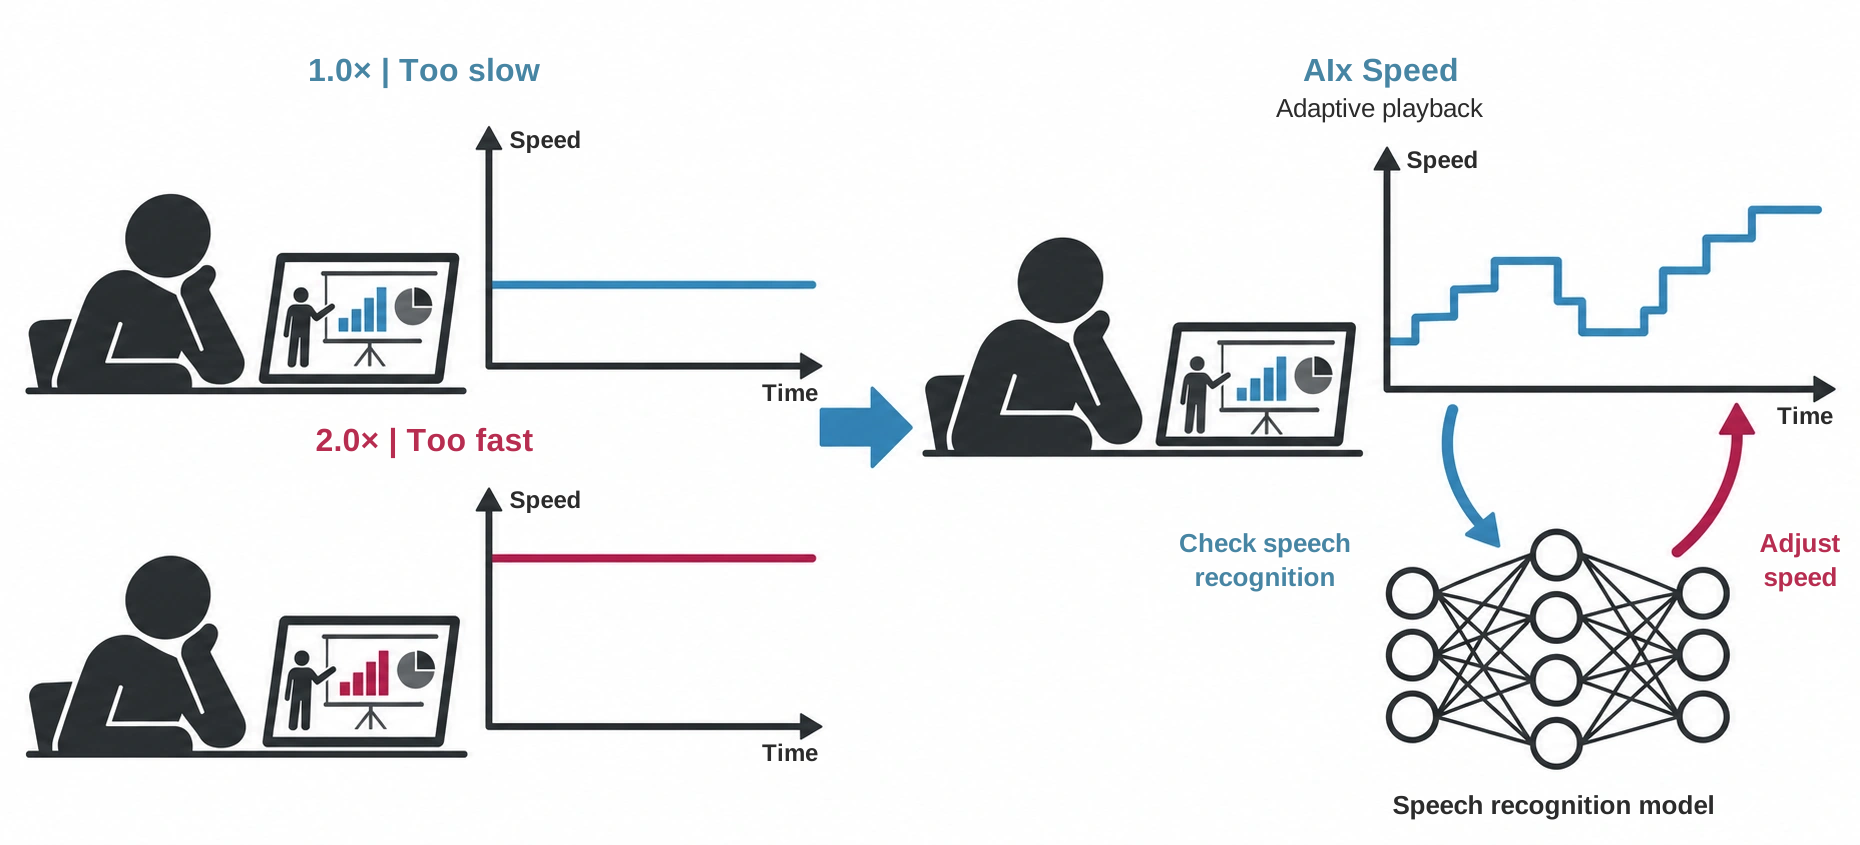
動画を一律に速くすると、聞き取りにくい部分まで同じように速くなります。AIx Speedは、音声認識モデルが言葉を読み取れるかを手がかりに、音素ほどの短い単位で再生速度を調整します。速さと聞き取りやすさの両立を目指した研究です。
Uniform speed-up accelerates difficult passages as much as easy ones. AIx Speed uses speech-recognition performance as a proxy for human listening to adjust playback at intervals as small as phonemes. The aim is faster speech that remains intelligible.
どのように動くかHow it works
- 予備実験では、140人の英語話者による書き取りと音声認識モデルを比較しました。通常速度より速い範囲では、速度が上がるにつれて両者の成績が下がる傾向が似ていました。
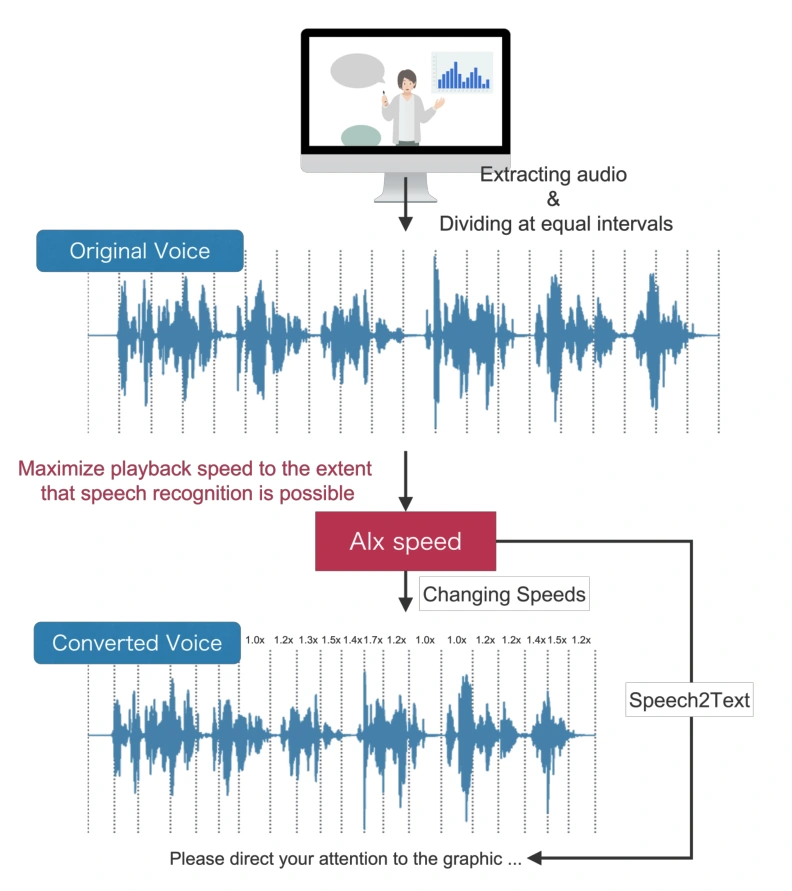
- 音声を短い区間に分け、音声認識ができる範囲で速度を上げるようにモデルを学習します。
- 区間ごとに速度を変えた音声をつなぎ、同じ平均速度で一律に速くした音声と比較します。
- A preliminary transcription study with 140 English speakers compared human and model performance across playback speeds. Above normal speed, both degraded in a similar pattern.
- Train a playback-speed adjuster to increase speed while preserving speech-recognition performance.
- Combine the adjusted segments and compare them with uniformly accelerated speech at the same average speed.
速度を決めるモデルと、確かめるモデルA speed adjuster and a speech recognizer
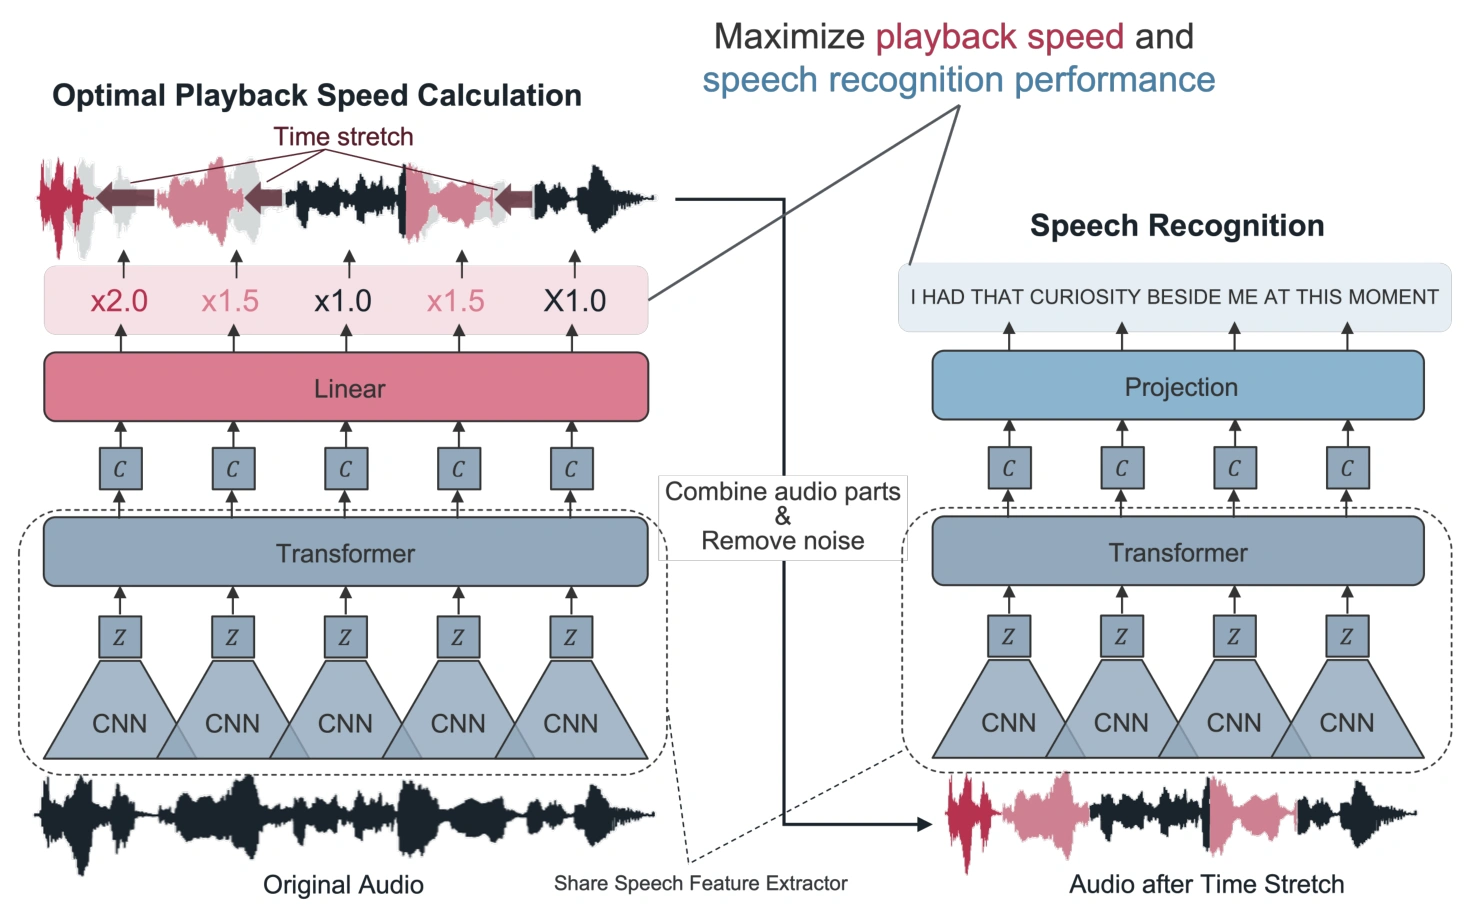
- 左側:区間ごとの速さを決める。Wav2Vec2のCNNとTransformerが、音声の特徴を読み取ります。その特徴をLinear層に渡し、短い区間それぞれの再生速度を出力します。
- 右側:速くした音声を文字にする。速度を変えた区間をつなぎ、ノイズを抑えた音声を音声認識モデルに渡します。認識した文字列を正解と比べ、言葉をどれだけ正しく読み取れたかを調べます。
- 速さと認識の正確さを両立させる。両側で音声の特徴を取り出す部分を共有し、「再生速度を上げること」と「認識の誤りを抑えること」を組み合わせて速度調整を学習します。
- Left: predict a rate for each segment.Wav2Vec2 uses a CNN and a Transformer to extract speech features. A linear layer maps these features to playback rates for short segments.
- Right: transcribe the accelerated speech.The adjusted segments are combined and denoised, then passed to a speech recognizer. Its transcription is compared with the reference text to measure recognition errors.
- Balance speed and recognition accuracy.The two branches share the speech feature extractor. The speed-adjustment objective combines increasing playback speed with reducing recognition errors.
何が分かったかFindings
- 同じ平均速度でも、一律の倍速より言葉を認識しやすくなりました。LibriSpeechでは平均1.30倍速で、音声認識の単語誤り率が14.58%から12.96%へ低下。UME-ERJでは平均1.29倍速で、63.90%から53.13%へ低下しました。
- 人が聴いたときの音声品質の評価も高くなりました。英語を日常的に使う米国在住者50人による5段階評価で、一律の倍速と比べ、AIx Speedは2つのデータセットでそれぞれ平均0.5点と0.8点高く評価されました。
- 全体の再生速度を落とさなくても、短い区間ごとに速さを調整することで、機械の認識しやすさと、人が聴いた音声品質の両方を改善できました。
- Speech recognition improved at the same average speed. At 1.30× on LibriSpeech, word error rate fell from 14.58% with uniform acceleration to 12.96% with AIx Speed. At 1.29× on UME-ERJ, it fell from 63.90% to 53.13%.
- Listeners also rated the speech quality more highly. Fifty US residents who used English daily gave AIx Speed mean ratings 0.5 and 0.8 points higher on a five-point scale than matched-rate uniform acceleration on the two datasets, respectively.
- Adjusting the speed of short segments improved both machine recognition and listeners’ ratings of speech quality, without lowering the overall playback rate.
引用Citation
@inproceedings{kawamura2023aixspeed,
  title = {AIx Speed: Playback Speed Optimization Using Listening Comprehension of Speech Recognition Models},
  author = {Kazuki Kawamura and Jun Rekimoto},
  booktitle = {Augmented Humans Conference},
  year = {2023},
  publisher = {Association for Computing Machinery},
  doi = {10.1145/3582700.3582722}
}本文と図は上記の原著論文に基づきます。図をクリックすると拡大できます。Text and figures are based on the original paper linked above. Select a figure to view it at full size.